


Someone asks a chatbot to work out the bill for a group meal after a discount and a service charge, and it comes back with an answer straight away.
On the page, it looks like solid maths. In reality, it is not.
Nothing about how the answer is written gives that away. A correct calculation and a badly wrong one read exactly the same.
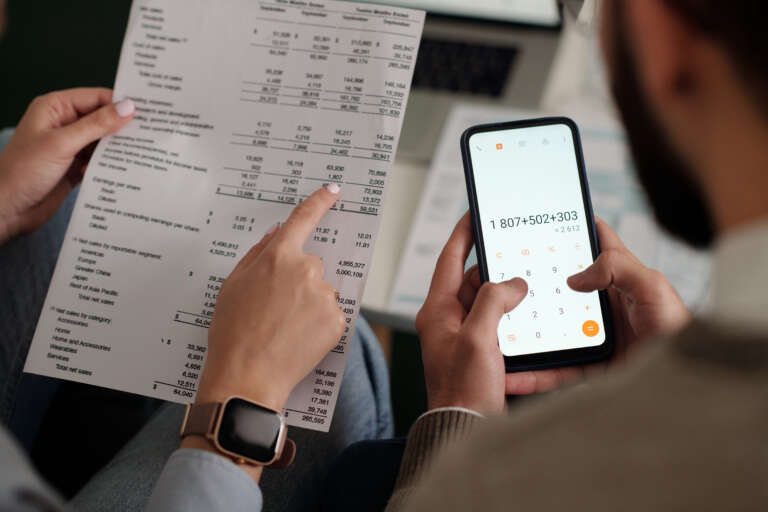
That mismatch is what throws people.
The same tool can explain a complicated topic in plain English, write a decent cover letter, and summarise a dense report in seconds. Then it fumbles a two-step multiplication a ten-year-old could check with a pencil.
The reality sits somewhere in the middle.
AI is not "bad at maths" in the way a person who never learned times tables is bad at maths.
It is doing something else entirely, not real maths. That works brilliantly for language, but not for maths calculations and logic.
This is where understanding how these tools actually generate an answer becomes useful.
Once the mechanism is clear, the pattern of errors stops looking random and starts looking predictable.
What AI Still Can't Do Well covers this briefly as one of several general limitations.
This guide covers two things: why AI gets sums wrong, and where multi-step reasoning breaks down.
Topics touched upon
Toggle1. Why AI getting maths and logic wrong catches people off guard
Chatbots sound confident even when the working is wrong
A chatbot asked to split a bill three ways, add a 12.5% service charge, then subtract a £10 voucher will often produce a clean, well-formatted answer. Correct, incorrect, it looks the same.
There is no hesitation in the tone, no hedge, no sense that one step was shakier than another.
That confidence is not a signal of accuracy. It is just how the text was generated.
What Is an AI Hallucination? covers the wider version of this problem, where an AI states something false with the same fluency as something true.
The gap between sounding smart and actually reasoning
Writing a fluent sentence and working through a logical sequence of steps are different skills.
A person can be an excellent writer and still get sums wrong.
AI models blur that line because both tasks come out of the same process: predicting what text comes next.
That does not mean the model is incapable of getting maths right. In most cases, on familiar problems, it does.
It means the reliability of the answer depends on how the problem is shaped, not just how hard it looks to a person.
2. How AI models actually generate an answer
Predicting the next likely word, not calculating a result
A large language model, the kind of AI behind tools like ChatGPT, does not run a calculation.
It predicts, one chunk of text at a time, what is statistically likely to come next, based on patterns learned from enormous amounts of training text.
Ask it "what is 47 plus 38" and it is not adding 47 and 38. It is predicting that a sequence which looks like this question is usually followed by a sequence that looks like "85".
Often that prediction happens to be correct. Sometimes it is not, and there is no internal check that catches the difference.
Why this works well for language but badly for maths calculations
Before a model reads any text, it goes through tokenisation, the step that chops the text into chunks (tokens) the model can process.
For words, this works well enough. For numbers, it can cause real problems.
Before AI reads a number, it chops it into small pieces first.
It is not counting units, tens, and hundreds the way a person would. It just splits the number based on patterns it has seen before.
A 2024 paper on the issue, NumeroLogic, looked into exactly this problem.
It found that different AI companies handle it in different ways, and none of them handle it quite the way a person would.
Google's and Meta's models treat every single digit as its own separate piece.
The models behind ChatGPT group digits into chunks of up to three characters instead.
Either way, those chunks do not always split in the same place, even for numbers that look almost identical.
A technical blog post by researcher Beren Millidge showed just how strange this gets in practice.
He found that an older model, GPT-2, split the number 2249 into "2" and "249". It then split 2250, a number just one digit different, into "22" and "50" instead.
Two numbers that look almost identical to a person get cut into completely different pieces before AI even starts working out an answer.
This is why maths calculations can quietly go wrong even when AI is fluent with everything else: it is not seeing the number the way a person reading it would.
Where multi-step problems break down
A single calculation has one chance to go wrong.
A multi-step problem, work out the subtotal, then apply the discount, then add the charge, has several chances, and each step's prediction feeds into the next one.
If an early step drifts even slightly, everything built on top of it drifts too, and the model has no separate mechanism to notice.
OpenAI tested GPT-4 on a set of grade-school-level maths word problems, called GSM8K.
It scored 92.0%, according to OpenAI's own GPT-4 Technical Report. It was given a few worked examples to follow before being tested, not asked completely cold.
That sounds like a strong result.
It is worth reading the fine print too. OpenAI's own report says some of those test questions had likely already come up during GPT-4's training.
So the real score, on genuinely new questions, is probably lower than 92.0%. Even taken at face value, that figure still means roughly 1 in 12 problems came back wrong.
3. Where this shows up in everyday use
Multi-step word problems and multiplication
Word problems that involve more than one operation, working out a total cost, converting a quantity, then applying a percentage, are where errors cluster.
Each extra step is another point where the prediction can quietly go off course.
Apple's GSM-Symbolic paper tested this directly.
Researchers took standard maths word problems and added a single extra clause that sounded relevant but did not actually change the answer, a bit like adding "some of the apples were slightly bruised" to a problem about counting apples.
That one addition caused accuracy to drop by up to 65% across every state-of-the-art model the researchers tested.
The same paper found something else worth knowing: simply changing the numbers or names in an otherwise identical problem also caused performance to shift and decline.
That points to models pattern-matching the shape of a familiar problem rather than reasoning from the actual logic in front of them.
Logic puzzles and riddles
Classic logic puzzles, "if all cats are animals and some animals are grey, are some cats grey", trip up AI models for a related reason.
The model has seen thousands of similarly worded puzzles during training and tends to reach for the pattern that usually follows, rather than working through this specific chain of premises from scratch.
A puzzle with a twist, one that deliberately breaks the usual pattern, is where this becomes obvious.
The AI often answers the version of the puzzle it expects to see, not the version actually asked.
Following a chain of "if this, then that" instructions
Some instructions come with conditions attached. For example: "if the total is over £50, delivery is free. Otherwise, add £4.99. Unless it's a subscriber, in which case delivery is always free."
Following that means keeping track of several rules at once, and applying them in the right order.
Each rule is another place a prediction can slip. It is the same underlying issue as multi-step maths, just with words instead of numbers.
Counting and comparing exact figures
Ask an AI how many times the letter R appears in "strawberry" and it will sometimes get it wrong, a failure that has become a well-known example of this whole category of problem.
A 2025 paper published in IEEE Computer confirms this is a real, studied issue, stating plainly that large language models "struggle on simple tasks such as counting the number of occurrences of a letter in a word."
The cause is the same tokenisation problem covered in section two.
The model is not scanning the word letter by letter the way a person would. It sees the word as a small number of chunks, and counting individual letters within a chunk is not something the underlying prediction process was built to do reliably.
4. Why some AI tools are better at this than others
Newer models built to think in steps
A newer kind of AI, often called a reasoning model, is trained to work through a problem in stages before giving a final answer, rather than jumping straight to a response.
These models tend to do noticeably better on maths tests than the older, faster-answering kind.
OpenAI's reasoning model o1, for example, scored 83% on a qualifying exam for a major international maths competition, compared with just 13% for the standard GPT-4o model on the same test.
Its newer successor, o3, scored even higher on similar maths tests.
DeepSeek, a rival reasoning model built by a different company, scored similarly well on its own maths testing, described in its own published research.
Worth knowing: these are the labs' own reported figures, not independently checked by anyone else yet. Treat them as a genuine sign of improvement, not a guarantee of how the tool performs on any given question.
Tools that call a calculator or code in the background
Some AI tools now quietly hand a maths question off to an actual calculator, or a small piece of code running in the background, instead of trying to answer from pure text prediction.
A study from Meta AI showed just how much this helps. Giving a model access to an external calculator more than quadrupled how often it got maths word problems right, across several different tests.
That study used an older, smaller AI model by today's standards, so the figures demonstrate the underlying principle rather than reflect what a current, well-known chatbot would score.
The principle still holds: a calculator gets the right answer because it calculates. A language model only gets the right answer if its prediction happens to land on the right number.
Why this still is not a guarantee of a correct answer
Reasoning models are not a clean fix.
Getting better at maths came with a trade-off, and OpenAI's own testing shows it clearly.
The company ran its newer models, o3 and o4-mini, through a test that checks how often an AI makes up false facts about real people.
The older model, o1, got this wrong 16% of the time.
o3, the newer model that is noticeably better at maths, actually got it wrong more often: 33% of the time, roughly double o1's rate.
o4-mini did worse again, getting it wrong 48% of the time, roughly triple o1's rate.
OpenAI's own explanation is that these newer models simply say more overall. They make more correct statements, but they also make more incorrect ones, and the two rise together.
OpenAI's own report is honest about not fully understanding why, stating plainly that more research is needed.
So getting sharper at maths did not make these models more trustworthy in general.
Getting better at one specific task does not mean getting better at everything, including how often the AI makes things up about real people.
What Is an AI Hallucination? covers this trade-off in more detail.
5. How to get more reliable answers on maths and logic tasks
Asking AI to show its working step by step
Asking for the working, not just the final number, gives a chance to spot where a calculation went wrong.
This is the same chain-of-thought approach used in the benchmarks in section two.
It does not guarantee a correct answer, but it turns a black box into something checkable.
Breaking a big problem into smaller questions
Instead of asking for a full multi-step calculation in one go, splitting it into separate questions, each subtotal, then the discount, then the final total, reduces the number of places an early mistake can quietly ripple forward unnoticed.
Checking the final answer independently
Any figure that actually matters, a bill, a budget, a quote, should be checked against a calculator or done by hand before being relied on.
AI works best as a helper here, not the final authority.
How to Reduce Wrong AI Answers has more general troubleshooting steps that apply well beyond maths.
When to use a calculator or spreadsheet instead
For anything involving:
- exact money figures, invoices, or tax calculations
- multi-step budgeting with several changing variables
- formulas that need to be reused or audited later
- data that needs to be double-checked by someone else
a proper calculator or spreadsheet is the better tool, and it is worth understanding why.
A calculator or a spreadsheet formula runs the same fixed steps every single time.
Type in the same numbers twice, and it will give the same answer twice. Nothing about how it works changes from one go to the next, so the result can be trusted to stay consistent.
An AI chatbot does not work that way.
It is predicting an answer based on patterns, not running a fixed set of steps, so there is no built-in guarantee it will land on the right number, or even the same number, every time it is asked.
That is really the whole difference. A spreadsheet calculates. An AI chatbot predicts what a calculation probably looks like.
For anything where being wrong actually costs money, time, or trust, a proper calculator or spreadsheet removes that uncertainty completely.
6. Limitations of AI on maths, logic, and reasoning tasks
Why AI can be confidently wrong
An AI chatbot has no way of checking its own answer.
It is not calculating, so there is nothing inside it that can stop and say "wait, that doesn't look right."
It is just generating the most likely-sounding piece of text to come next.
That comes out sounding fluent and sure of itself, whether the number behind it is correct or not.
There is no hesitation built in, and no change in tone to watch out for. A wrong answer reads exactly the same as a right one.
Why this is not a bug that gets fully fixed
The two things causing all of this, splitting numbers into odd chunks, and predicting an answer rather than working it out, are not small glitches sitting on top of an otherwise reliable system.
They are how the whole thing works underneath.
That is why things improve gradually rather than all at once. Extra reasoning steps, handing sums off to a calculator, better training data, each one helps a bit. None of them is a single fix that solves the issue outright.
Even the newest AI models still do this. A study by Apple found they tend to guess based on what a similar problem usually looks like, rather than actually working through the logic in front of them each time.
Tasks where AI should not be trusted alone
- money matters: bills, invoices, tax, or payroll, where getting the exact figure wrong has real consequences
- code that depends on the maths being correct, not just looking like it works
- puzzles or tests that are genuinely meant to check understanding, not just produce an answer
- any multi-step calculation that feeds into a decision that is hard to undo afterwards
- comparing two similar-looking numbers, exactly the situation where AI is most likely to make the digit-splitting mistake covered earlier in this guide
Anything where the number actually matters belongs in a calculator or a spreadsheet, not a chat window.
Final thoughts
AI struggling with maths and logic is not a random quirk.
It comes directly from how these tools work: predicting the next likely piece of text rather than calculating a result.
That mechanism is superb for language and unreliable for maths calculations, and no amount of polish changes that underlying trade-off.
The honest picture has real improvement in it too.
Reasoning models genuinely do better on maths benchmarks than earlier generations, and tools that quietly hand a sum off to a calculator sidestep the whole problem rather than trying to predict their way through it.
Neither of those developments makes AI a substitute for checking a number that actually matters.
AI can be wrong even when it sounds completely sure of itself, and multi-step problems are exactly where that risk compounds.
Treat any AI-generated calculation as a starting point rather than a finished answer, ask for the working, and reach for a calculator or spreadsheet whenever the figure genuinely needs to be right.
Can AI Be Wrong? covers the broader version of this caution for anyone who wants the fuller picture beyond maths specifically.
Frequently asked questions
Why is AI bad at maths?
AI language models predict the next likely piece of text rather than performing a calculation. Numbers are also broken into chunks (tokenisation) that do not follow place value, so similar-looking numbers can be processed in inconsistent ways. That combination makes maths calculations unreliable even though the same model handles language fluently.
Can AI actually reason, or is it just predicting text?
Standard language models are predicting text, not reasoning in the way a person works through a problem. Newer reasoning models generate an extended chain of working before answering, which improves results on maths benchmarks, but they are still built on the same underlying prediction process, not a separate logical engine.
Are newer AI models better at logic and maths?
Yes, on maths-specific benchmarks. OpenAI's o3 reached 96.7% on the AIME 2024 competition benchmark, and DeepSeek-R1 scored 79.8% on the same test. However, OpenAI's own data shows these same reasoning models can hallucinate more often on factual-recall tasks, so the improvement is domain-specific rather than a general boost to reliability.
Should AI be trusted with multi-step calculations?
Not without checking. Each step in a multi-step calculation is a fresh chance for a small error to creep in, and those errors carry forward into later steps. AI works best as a helper for this kind of task, with the final figure checked independently before it is relied on.
How can someone check if an AI's maths is correct?
Asking the AI to show its working step by step makes it possible to spot exactly where an error happened. Breaking a large problem into smaller questions also helps. For any figure that genuinely matters, running it through a calculator or spreadsheet separately is still the safest approach.
